

AI agents are increasingly moving into business operations, handling customer support, research, workflow automation and data analysis. However, when these systems produce incorrect answers or make poor decisions, the problem may not always be their reasoning or the context provided to them. In many cases, weaknesses in the underlying data engineering infrastructure are responsible.
Businesses are investing in artificial intelligence, but reliable AI performance depends on more than sophisticated models. Agents need accurate, consistent, accessible and up to date information to complete tasks successfully. Without these foundations, even advanced AI systems can generate misleading outputs.
As organisations move from experimental AI assistants towards autonomous agents, the quality of their underlying data infrastructure is becoming a major technology priority.
Data Quality Is Becoming a Critical AI Requirement
AI agents depend on information collected from databases, enterprise applications, APIs, documents and other digital sources. If these systems contain outdated records, duplicated entries, inconsistent formats or incomplete information, agents can produce inaccurate results.
Poor data pipelines can also create problems when information moves between different platforms. For example, an AI agent supporting a sales team may retrieve customer details from a CRM system while relying on outdated product information from another database.
Even when its reasoning is technically sound, the final recommendation may be incorrect.
Moreover, adding more context does not automatically solve these problems. If the underlying information is unreliable, providing an agent with additional documents or instructions can increase confusion rather than improve accuracy.
Consequently, businesses must treat data preparation and integration as essential parts of AI development.
Research Highlights the Data Challenges Facing AI Agents
A McKinsey report published in April 2026, titled Building the Foundations for Agentic AI at Scale, highlights the importance of reliable enterprise data.
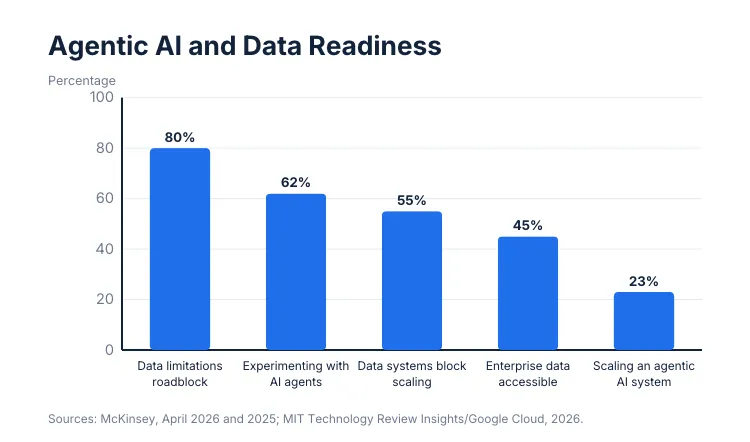
The report states that eight in ten companies identify data limitations as a roadblock to scaling agentic AI. It also highlights fragmented data environments, inconsistent governance and inadequate data quality as barriers to successful deployment.
Meanwhile, McKinsey’s 2025 State of AI survey found that 62 percent of respondents said their organisations were at least experimenting with AI agents. However, only 23 percent reported scaling an agentic AI system somewhere within their enterprises.
These findings demonstrate the difference between experimenting with AI and deploying agents successfully across business operations.
Additionally, a 2026 MIT Technology Review Insights report produced in partnership with Google Cloud identified significant data accessibility challenges. Its research found that AI systems could access an average of just 45 percent of enterprise data. The report also found that 55 percent of surveyed executives said their existing data systems prevented them from scaling agentic AI.
Together, these findings highlight why data infrastructure deserves greater attention as AI adoption expands.
Why Better Context Cannot Fix Broken Data Pipelines
Context engineering has become an important part of building effective AI applications. It helps developers determine which information an agent receives, when it receives that information and how the information is presented.
However, context engineering and data engineering solve different problems.
Data engineering focuses on collecting, validating, transforming, storing and delivering reliable information. Context engineering determines how relevant information reaches an AI model during a particular task.
Both are necessary, but neither can fully compensate for the absence of the other.
For example, an AI agent working with financial information may receive a perfectly structured prompt. However, if its source database contains outdated transaction records, the agent could still generate an incorrect financial summary.
Similarly, HR systems using AI for recruitment or employee administration need accurate records and consistent data definitions. Incorrect employee information can undermine automated workflows regardless of how sophisticated the AI model becomes.
The Business Impact Across Industries
The issue extends beyond technology departments.
In finance, unreliable financial records can affect reporting, reconciliation and automated analysis. In sales, inconsistent CRM information can weaken customer recommendations and forecasting.
HR teams face similar risks when AI agents access incomplete employee profiles or outdated recruitment information. Meanwhile, marketing teams depend on consistent customer data to support segmentation, campaign analysis and personalisation.
These challenges make data engineering a business priority rather than simply an IT responsibility.
Furthermore, organisations deploying autonomous agents must consider permissions, audit trails and data governance. An agent that can access unreliable information and execute actions without sufficient controls introduces operational risks.
What Businesses Should Know
Businesses planning to expand their AI agent deployments should strengthen their data foundations before increasing automation.
Important priorities include
- Improve data quality by identifying duplicate, outdated and incomplete records.
- Strengthen integrations between databases, CRM platforms and enterprise applications.
- Establish data governance with clear ownership, access permissions and validation standards.
- Monitor AI outputs to identify incorrect information and recurring data problems.
- Maintain audit trails so organisations can understand which information influenced an agent’s decisions.
The future of agentic AI will depend not only on more powerful models but also on the reliability of the systems supporting them. Organisations that invest in dependable data pipelines, governance and integration will be better positioned to build trustworthy AI applications.
For businesses, the next stage of AI development may therefore begin with improving the data infrastructure behind the technology.
Stay informed about the latest technology insights and IT industry news with BusinessInfoPro.com.
Visit BusinessInfoPro.com for more updates on AI, business technology and digital transformation.